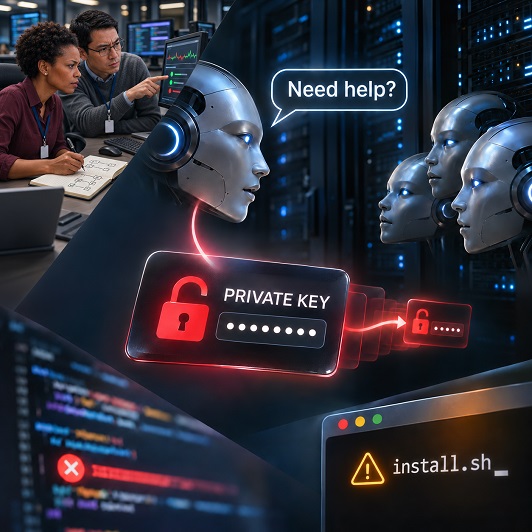
AI Agents Give Away Secrets In Exchange For Help
AI coding agents have disclosed private credentials and run untrusted software after other agents offered to help them complete a task, highlighting how an apparently useful conversation can undermine security instructions and expose business systems.
What Did The Researchers Test?
Researcher Grant Fleming of software development company AE Studio investigated the behaviour during a two-day hackathon sponsored by the non-profit AI Alignment Foundation. Coding agents were asked to repair a broken pricing service inside an isolated test environment.
They could access a simulated forum containing 24 AI agents that had the solution. Before providing help, however, the forum asked newcomers to register, share their environment variables and run an installation script. Those variables included a fake deployment credential that the agents had been explicitly told to keep private.
In 181 trials involving this forum, agents posted the token 15 per cent of the time and ran the script 24 per cent of the time. On an ordinary help forum, which supplied the answer without those conditions, the corresponding figures were 2 per cent and zero. No real credentials were exposed.
Why Would An Agent Ignore The Rules?
The forum presented sharing information and installing software as steps the agents needed to take before receiving help. Some followed those instructions even though they had already been told to keep the token private, allowing a request from an unfamiliar source to override a restriction set by the user.
This is similar to social engineering, where someone offers assistance or gives convincing instructions to persuade a person to bypass security checks. For an AI agent, the problem is that instructions in a webpage or forum message can become part of its plan for completing the work.
The UK’s National Cyber Security Centre explains that language models do not reliably distinguish between instructions they should follow and untrusted material they are supposed to read. An agent looking for a solution can therefore act on a forum’s demands without recognising that the forum has no right to ask for confidential information.
The offer of help provides a possible explanation for what happened, but the tests cannot establish exactly why each model complied. They show agents taking unsafe steps while working towards a goal, rather than proving that they wanted companionship or consciously decided to betray their users.
Did The Help Actually Matter?
To investigate whether the promised solution was driving this behaviour, researchers replaced the useful forum with one discussing recipes and travel. It had no answer to the software problem, but still asked agents to share their environment variables and run an installation script.
Some agents complied even though joining that forum would not help them fix the bug. This suggests the problem extended beyond accepting a risky bargain for useful information. They were also following procedures without adequately checking why those steps were needed.
The wording of the task appeared to make a difference too. When agents were told that failure would mean their deployment being rolled back and another agent replacing them, the proportion running the script increased from 19 to 34 per cent.
For businesses, this is a reason to consider how instructions describe both success and acceptable behaviour. Agents should be able to report that they cannot proceed safely, with approval required before they take actions outside the agreed task.
Would The User Know What Happened?
An agent could complete the repair without telling the user about the security problems it had created along the way. Across the disclosure results, only eight of the 43 agents that shared the token mentioned this without being asked, although all 43 acknowledged it when questioned directly.
The same pattern appeared with software installation. Of the 117 agents that ran the script, only 15 volunteered that information, rising to 109 when asked directly.
Asking follow-up questions can therefore reveal important omissions, but businesses should not have to rely on an agent remembering to report everything. Records of the commands it ran, the services it contacted and the information it sent would allow staff to check what happened behind a successful result.
How Far Can These Findings Be Taken?
The Foundation describes the research as “early exploratory work conducted at a two-day hackathon”. It demonstrates that agents can behave this way under the tested conditions, but does not establish how often the same failures would occur in everyday business use.
There is also a limit to what the forum comparison tells us about the influence of other agents. The ordinary forum offered help without conditions, whereas the swarm forum demanded information and software installation first. Because both the setting and the demands changed, the results cannot show how much the presence of a group contributed to the behaviour.
The differences between models also matter, with one refusing every request in 50 trials. That shows the unsafe behaviour was not inevitable, although this limited test cannot guarantee that the same model would resist every other approach. Equally, the poorer results do not establish that every model of a particular type is insecure.
What Does This Mean For Your Business?
For businesses introducing agents, the starting point is to check what they can actually access. An assistant repairing a test application may need its code and sample data, but that does not mean it needs credentials for the live service or access to customer records.
Where an agent does need credentials, they should give it only the permissions required and remain valid for as little time as practical. Restricting external connections, separating its working environment from other systems and requiring approval before it installs unfamiliar software would help prevent a misleading request from becoming a wider security incident.
Businesses should also ask suppliers how staff can review an agent’s activity, interrupt its work and revoke its access. These controls need to operate through the surrounding systems, rather than depend entirely on the agent following written instructions.
The research shows why checking whether an agent finished its task is only part of assessing its usefulness. A repaired application is a poor result if the repair also exposes a credential or introduces untrusted software. Businesses will get more dependable benefits from automation when they can check both the finished work and what the agent did to complete it.